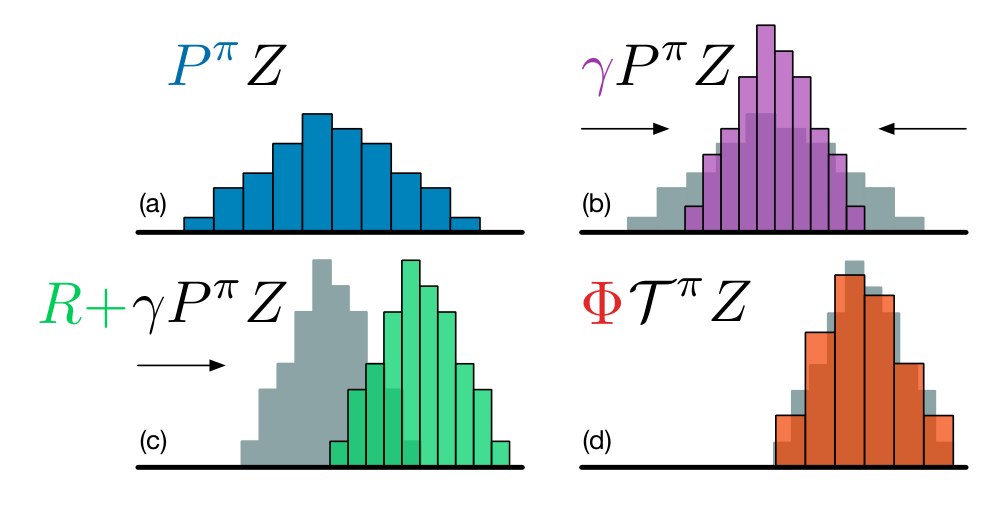
Distributional reinforcement learning
Learning distributions over returns, rather than only expected values, to better represent uncertainty in reinforcement learning problems.
Speech and Image Processing Department (PSI - ESAT), KU Leuven
I'm a final-year Ph.D. student supervised by Prof. Tinne Tuytelaars. My research focuses on value-gradient methods in reinforcement learning. I use learned environment models to provide richer training signals than scalar rewards or value targets alone. More broadly, I am interested in decoupled training of neural networks, with the goal of reducing the memory footprint of learning and making training less dependent on end-to-end backpropagation.
Recognized as a Top Reviewer at NeurIPS 2026.
Attended EWRL 2026 in Lille and presented two papers (ICLR 2026 and ICML 2026). Value gradients Sliced divergences
New blog post on multivariate distributional RL using sliced divergences. Read the post
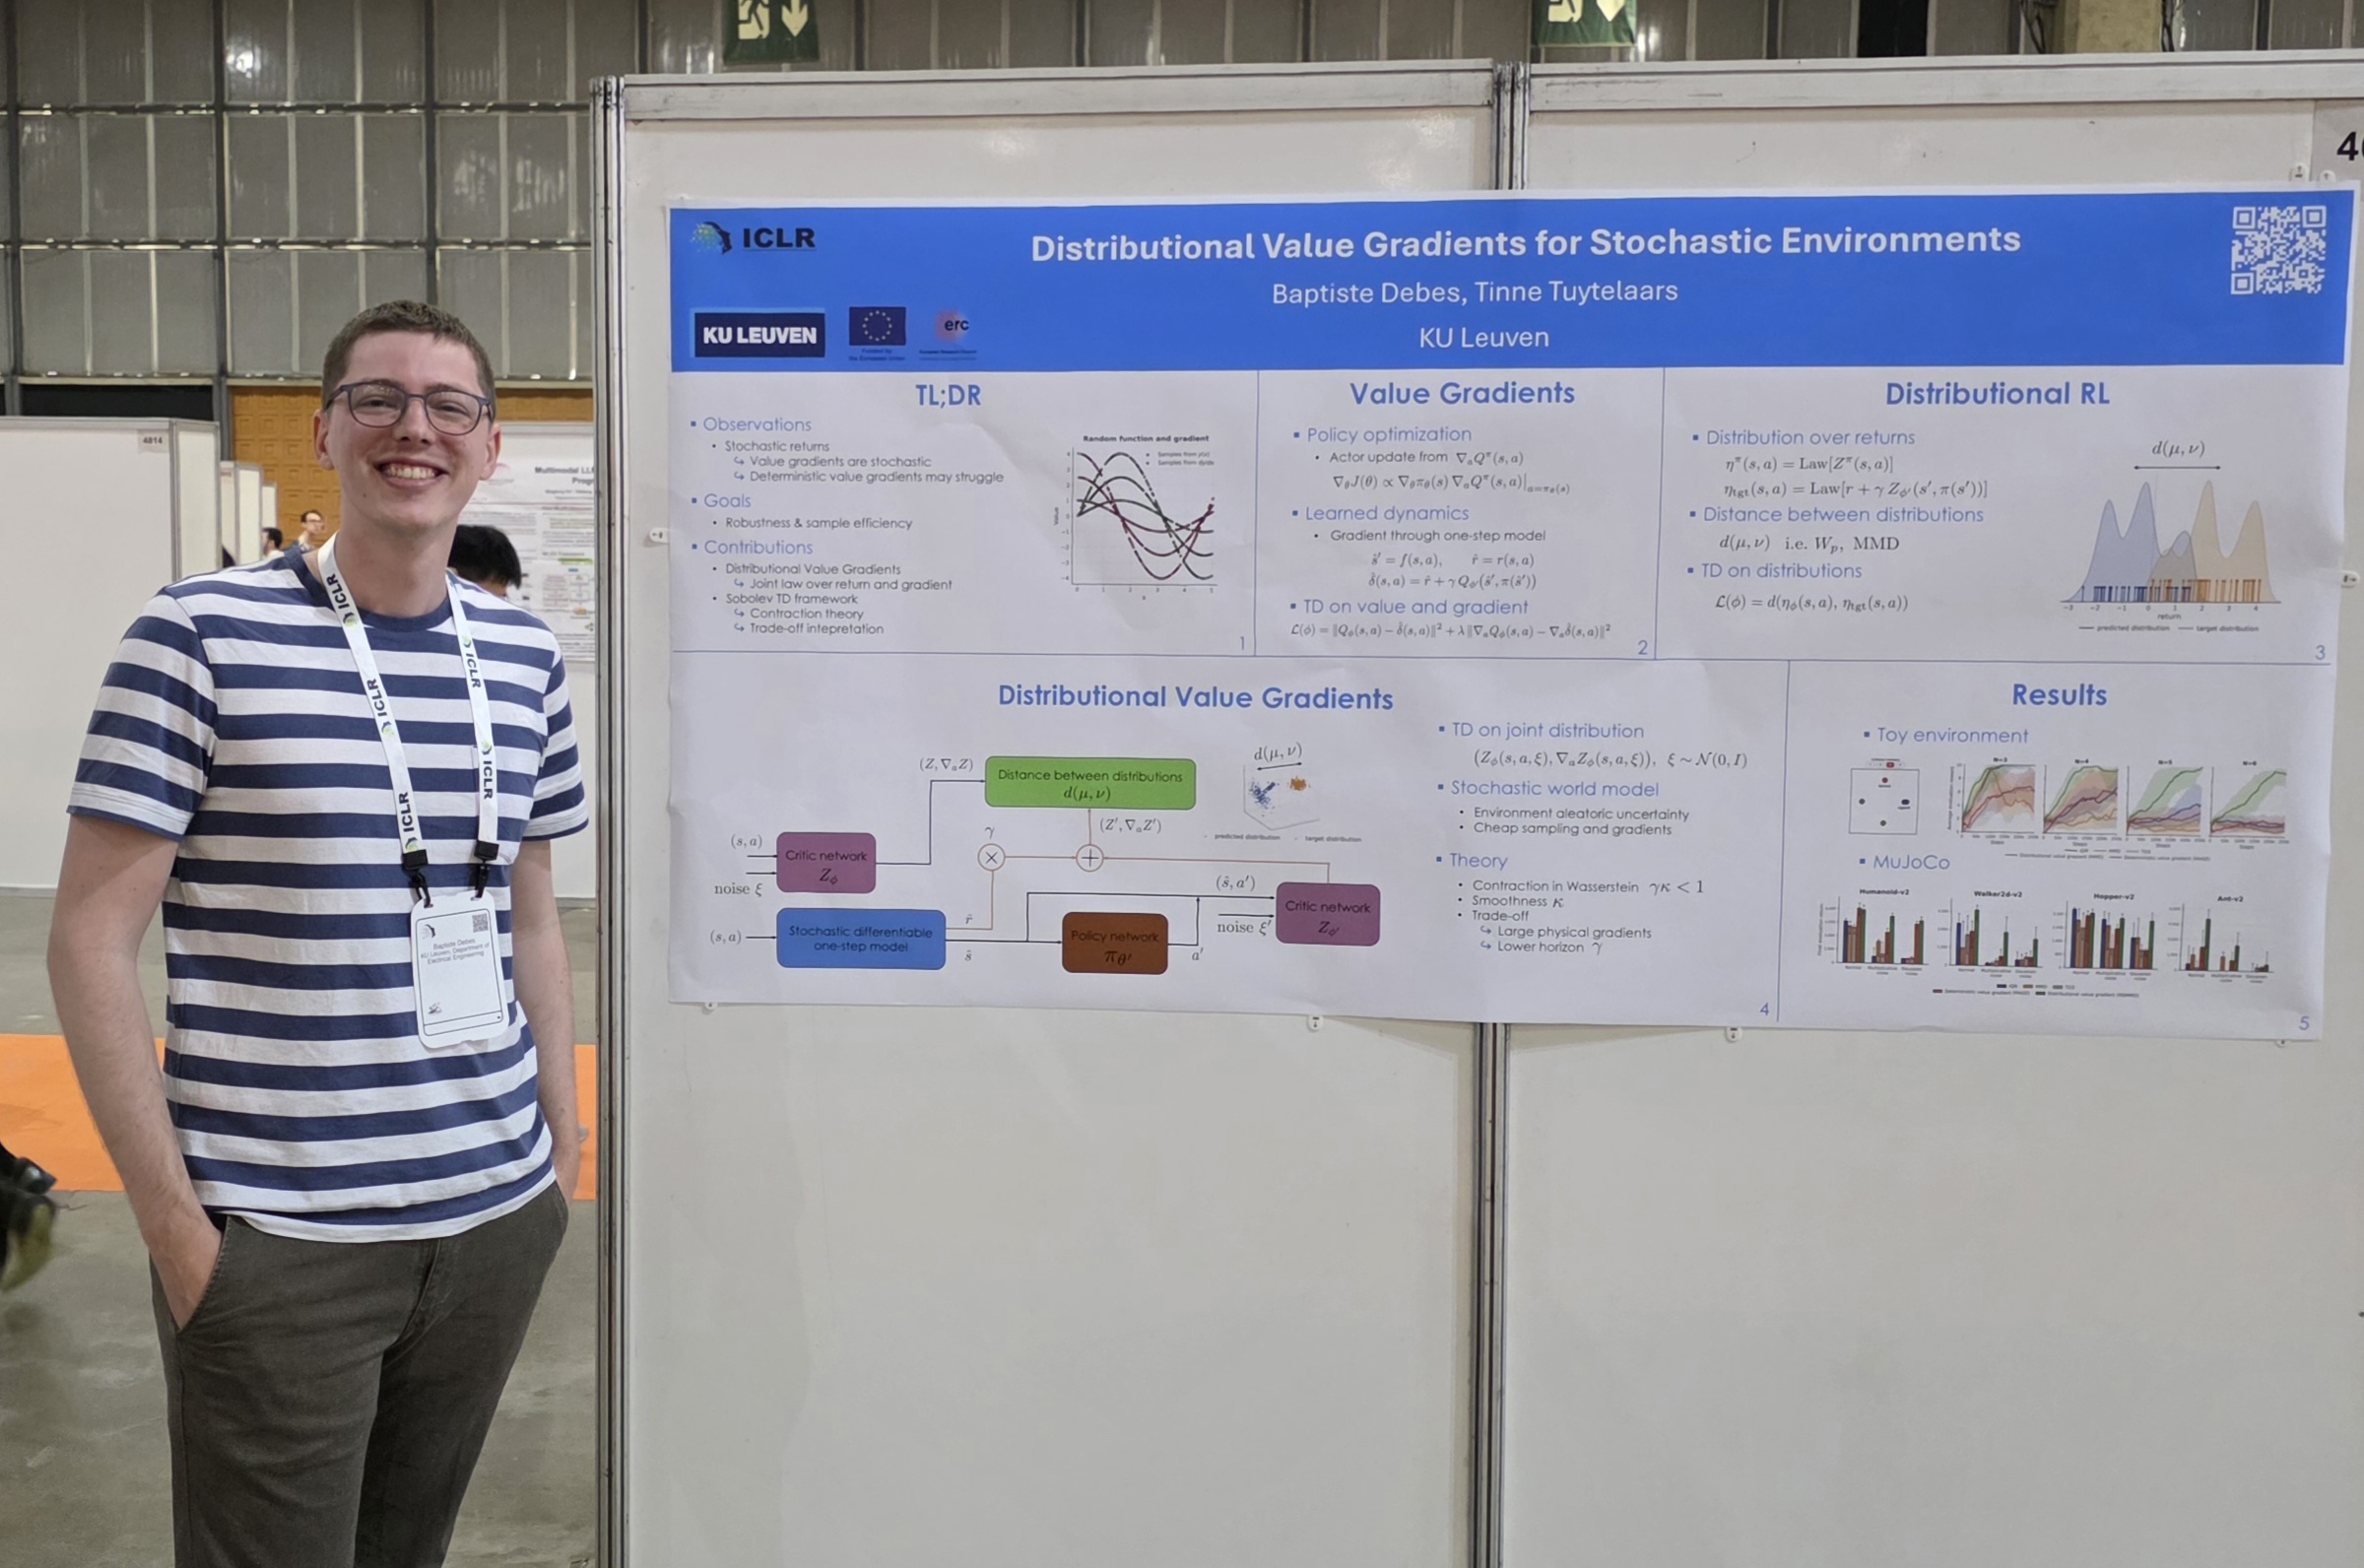
Presented the distributional value-gradients paper at ICLR in Rio de Janeiro. Photos and post
Accepted at ICLR 2026: Distributional Value Gradients for Stochastic Environments. arXiv
Learning distributions over returns, rather than only expected values, to better represent uncertainty in reinforcement learning problems.
Using learned environment models to estimate gradients of return targets with respect to actions, giving policy learning access to richer local information.
Training neural-network modules with local or predicted learning signals, aiming to reduce update locking and memory requirements during optimization.
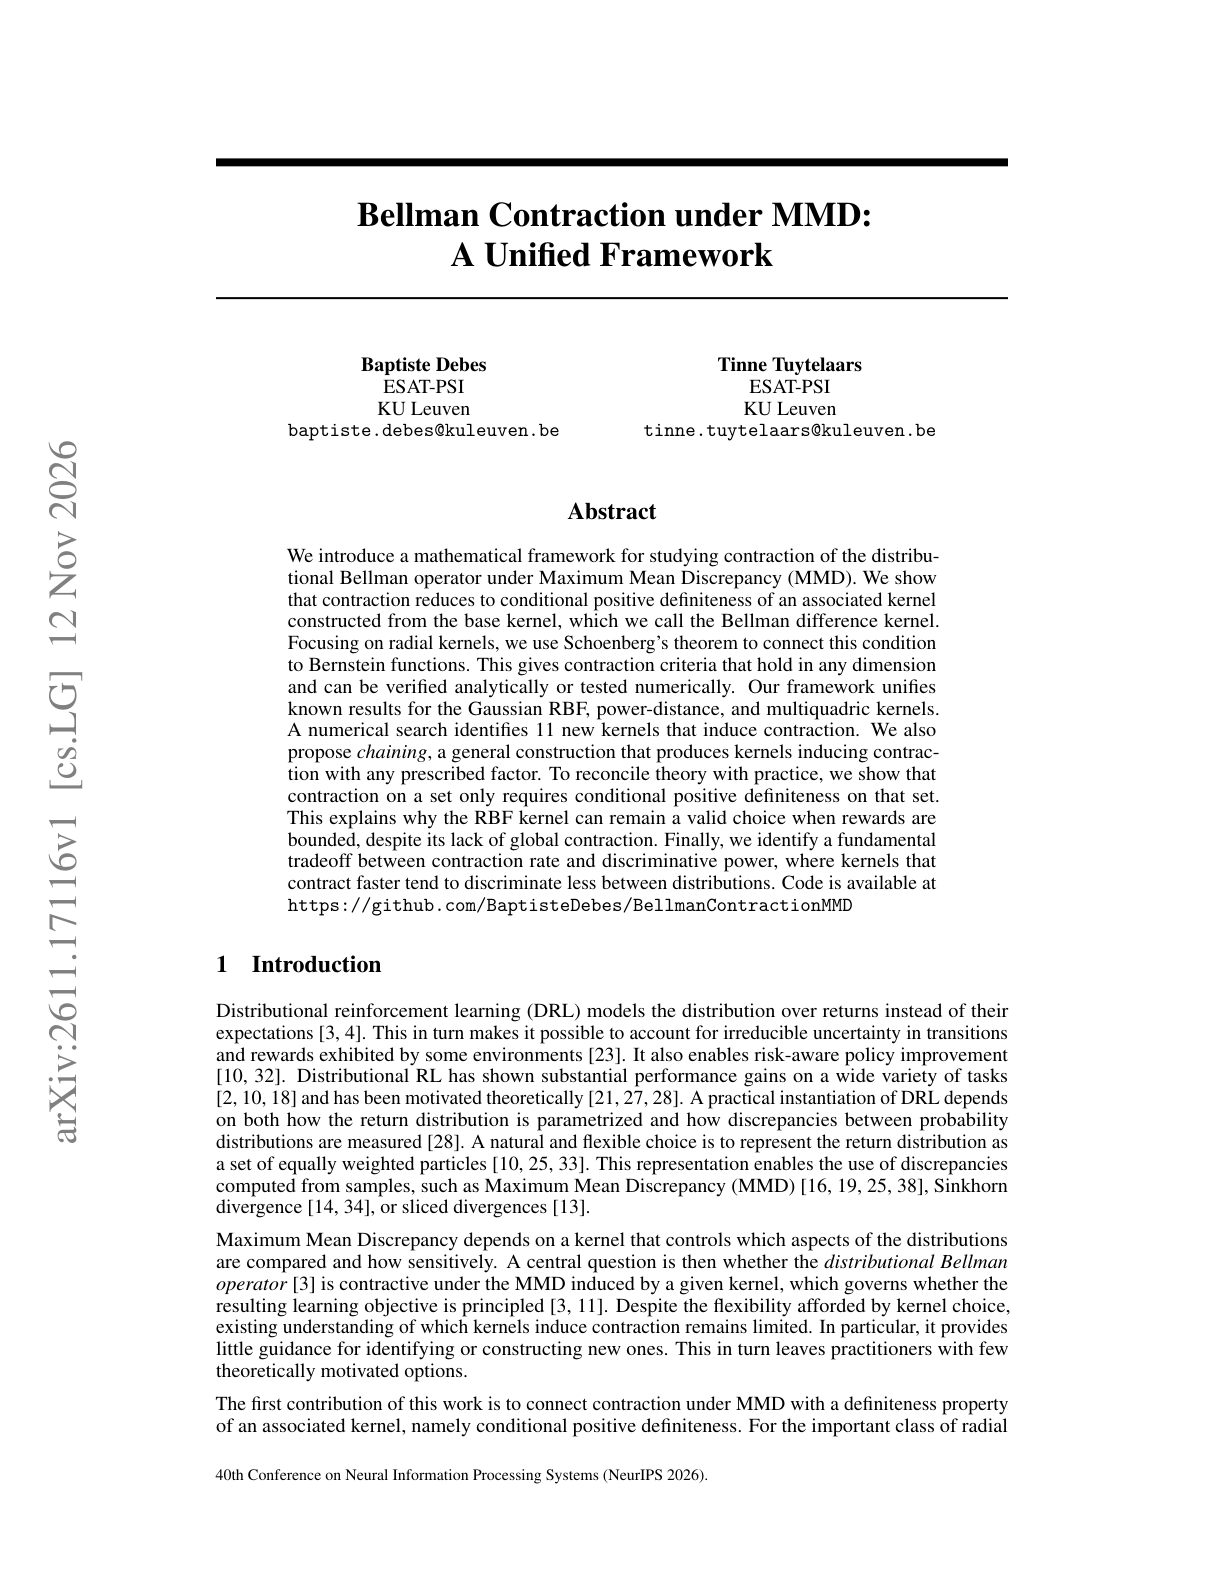
Sliced divergences make it practical to compare multivariate return distributions. They offer an attractive solution for multi-objective distributional RL and beyond. Their use in TD learning still leaves some open questions.
I presented my first paper at ICLR in Rio.